A long time ago, in a galaxy far away, I was contracted by a dying company to “make their app faster”, whatever that means. I’d be working closely with the Head of Engineering, also known as HoE (get your mind out of the gutter), to hunt down the application’s Sources of Slowness™.
There’s an old saying that goes something like this:
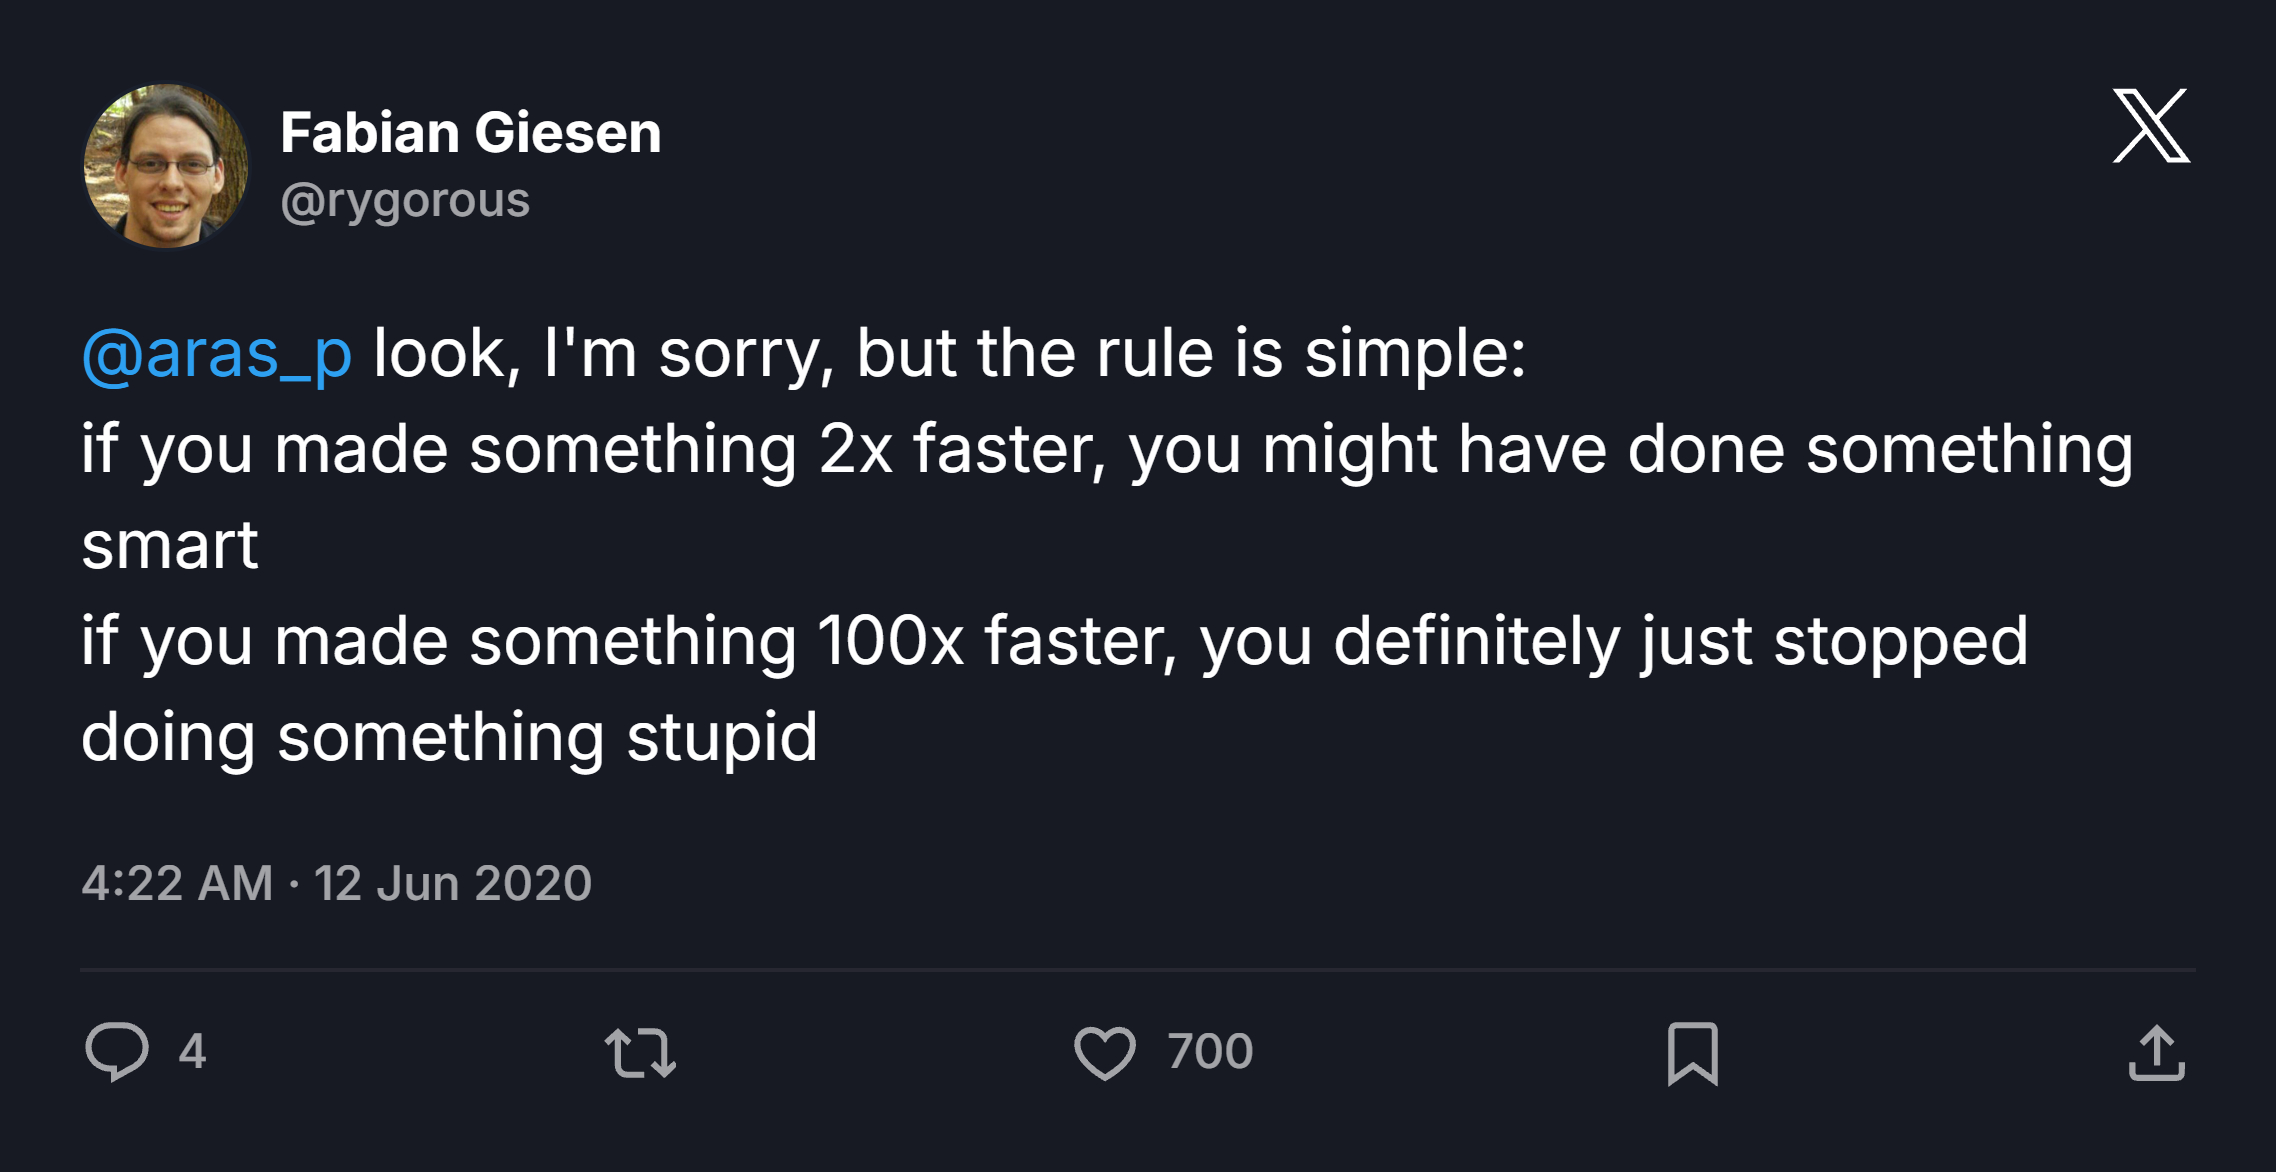
There’s another famous saying, which I even used as the opening quote of my Bachelor’s thesis 10 years ago:
Premature optimization is the root of all evil.
Both can be true. It’s all a matter of making the right decision at the right moment.
First, some context.
From a technical perspective, the application was a document processing pipeline. Documents came in through all kinds of input streams: emails, FTP, uploads, and probably snail mail for all I know. I never worked on ingestion. These documents came in various formats: PDF, DOCX, XLSX, and whatnot. But the interesting part was that most of the data was tabular.
Some tables spanned multiple pages. Some rows belonged to the same logical entity despite appearing in completely different tables. The application had to make sense of that mess, identify related contexts, slice and splice everything together, and store the processed results in a database.
Most documents were small, maybe up to ten pages. Processing them took a few minutes during peak hours. Nothing spectacular, but acceptable. Then there were the outliers. Documents with hundreds of pages. I’ve seen some reach 300. Those could take hours to go through the pipeline.
To figure out where all that time was going, we started pushing 100–200-page PDFs through the pipeline, checking the logs, and looking for the stages that were taking the longest.
A highly sophisticated benchmarking methodology, I know. But it worked.
We found plenty of things worth fixing. Some were fairly ordinary performance problems; others were almost embarrassingly simple once we understood what was happening.
I’ll spare you the full list. A few of them, however, make for good stories.
The Ten-Minute Transaction
One of the more interesting discoveries was a database operation with a p99 latency of 10.85 minutes.
Let that sink in. A single operation, involving database transactions and application logic, taking almost eleven minutes at the 99th percentile. I’ve seen people complete job interviews in less time than that.
When I started investigating, I found something odd. We were executing 33 database queries for every page of a document. Not per document. Per page. For a 100-page document, that’s 3,300 queries.
There wasn’t one particularly evil query responsible for the whole thing. It was a collection of smaller sins, working together to make sure nobody got home early. We had:
- Long-running transactions that kept database resources occupied far longer than necessary.
- Application logic executing inside transactions, even when the database transaction didn’t need to remain open.
- Overly broad Django ORM queries and eager-loading strategies that pulled in much more data than the operation needed.
- Related data being fetched repeatedly while iterating through document pages.
- Missing indexes on queries that were already doing too much work.
That was an interesting lack of foresight: a generic query used throughout the codebase to fetch practically everything about an entity. It worked, technically. And when you need everything, fetching everything is a perfectly reasonable approach.
Unfortunately, most callers didn’t need everything. Some needed a handful of fields. Others needed a couple of associations. But everyone got the full treatment, including joins and related records that had nothing to do with the operation being performed.
The biggest problem was that our query count scaled with the number of pages being processed. Every page would trigger another round of fetching data, including information we’d already fetched for previous pages. We could fetch what we needed once, load the necessary related records, and reuse them throughout processing. So that’s what we did.
We moved unnecessary application work outside transactions, tightened the data retrieval, removed redundant eager loading, added the missing indexes, and made sure batch-related data was loaded at the batch level rather than on every iteration. The generic “fetch everything” query was replaced in the affected paths with queries that actually reflected what the caller needed.
The query count went from 33 per page to 17 per batch. A 100-page document no longer needed 3,300 queries for this operation. It needed 17.
Before these changes, the affected operation had a p99 latency of 10.85 minutes. Afterward? 15.78 milliseconds. Yes, milliseconds. If you enjoy dividing large numbers by small numbers, that’s an improvement of roughly 41,000 times in p99 latency.
Sharing Memories Is Caring
Elsewhere down the pipeline, there were some Machine Learning steps, involving both classical NLP techniques and modern LLM-based processing. Not everything needed an LLM, despite what every AI startup pitch deck would have you believe. One of our steps used TF-IDF, a technique that’s been around for decades and still works surprisingly well for certain text-processing problems.
We had good enough results that replacing it with something fancier wasn’t particularly attractive. There was just one problem. It was eating RAM for breakfast.
The service ran on Kubernetes, with a Horizontal Pod Autoscaler allowing it to scale up to ten pods. These were fairly large pods, consuming around 12 GB of RAM each and more CPU than I care to remember.
I wanted to understand where all that memory was going. As it turned out, quite a lot of it was being used to store the same data over and over again.
The application was running through Gunicorn, with two Python worker processes inside each pod. Each worker loaded the model data into its own memory. Two workers, two copies of essentially the same read-only data. Multiply that by ten pods, and we had twenty worker processes loading their own model data.
What made this particularly annoying was that the model didn’t need to be loaded independently by every worker. For inference, much of that data was effectively read-only. So why were we paying the memory cost over and over again? Linux, fortunately, had thought of this problem long before I did.
Enter CoW: Copy-on-Write. When a process forks, the child process can initially share physical memory pages with its parent. As long as those pages aren’t modified, there’s no need to make additional copies. If either process writes to a shared page, the operating system creates a private copy of that page for the writer. Copy on write, very descriptive naming.
Now here’s the interesting part: Gunicorn can preload an application before forking its workers. This means we could load the model once in the parent process, then fork the two workers afterward. Both workers would inherit references to the already-loaded model data, and the unchanged memory pages could remain shared. Instead of loading the same model twice per pod, we could let the operating system do what it was designed to do. The fix was a simple 3 word addition to the Gunicorn config file.
Of course, this doesn’t magically make all memory shared forever. The workers still allocate their own memory, and anything that modifies shared pages can trigger copies. But for large, mostly read-only model data, it’s a very useful trick.
We changed the Gunicorn startup behavior so the model data was loaded before the worker processes were forked, allowing Copy-on-Write to do its thing. We deployed. And then I watched the replica count. Ten pods. Nine… Eight… Seven…
Eventually, the deployment settled at around three or four pods, still running two workers each. And memory consumption dropped from roughly 12 GB to 7 GB per pod. Same model. Same general processing job. Fewer pods, less memory. Heavy weights indeed.
Threads vs Processes vs Microservices
If you went to school, you probably know the difference between threads and processes. If you were alive during the Great Microservices Rewrite of the late 2010s, you’re probably wondering why I’m comparing threads, processes, and microservices in the same section. It’ll be clear in a moment. Keep reading.
Remember those documents we were processing? Some weren’t even proper digital documents. They were scans of paper documents. Images embedded in PDFs, containing tables we needed to extract. Before doing anything useful with those tables, we had to turn images into text. OCR, in other words.
This was another expensive stage in the pipeline. At one point, its p95 processing latency was hovering around 20 minutes. Twenty minutes to process scanned documents. Not exactly what I’d call fast.
The OCR processing service was written in Python 3.10 and used a thread pool. As far as I remember, it had something like ten threads processing images concurrently. Ten threads. Ten CPUs. Ten times the performance, right?
Well, no. The service was painfully slow for large documents, and throwing more CPU resources at its threaded design wasn’t producing the improvements we wanted. Something about that implementation wasn’t giving us the parallelism or throughput we needed, regardless of how many resources we threw at it.
We could’ve gone with Python multiprocessing. Multiple processes, independent workers, better use of multiple CPUs. Perfectly reasonable. But I’m not a fan of Python, and I didn’t particularly want to spend my afternoons worrying about which threads belonged to which processes, which processes needed restarting, and whatever other shenanigans we’d have to deal with.
And the pipeline was already running in Kubernetes, the spiritual successor of Plan9 from Bell Labs, so we decided to let Kubernetes handle the orchestration of independent workers.
We split the processing into an orchestrator pod and a bunch of worker pods. The orchestrator would receive a PDF, split it into pages, determine what kind of processing each page required, and enqueue jobs for the appropriate workers. The workers would pick up jobs, process the pages, return the results, and call it a day. One service coordinated the work. Other services did the actual work. Microservices FTW!
The result? Our p95 latency for the OCR processing step dropped from roughly 20 minutes to roughly 2 minutes. Around an order of magnitude faster, give or take.
Not bad for rearranging some processes and queues. Would multiprocessing have achieved similar results? Maybe. But the new design also gave us independent workers, separate resource allocation, and better control over which processing steps needed scaling.
Sometimes you don’t need a microservice. Sometimes you do. And sometimes you just need to stop pretending ten threads are ten independent workers.
So, What Did We Learn?
None of these changes required revolutionary algorithms.
We didn’t rewrite everything in Rust. We didn’t replace all our databases with some exotic distributed storage system. We didn’t throw an LLM at every performance problem either.
We mostly stopped doing unnecessary work. We stopped fetching the same records thousands of times. We stopped loading the same model into separate chunks of memory. We reorganized document processing so independent work could actually execute independently.
We really did stop doing something stupid. But that doesn’t necessarily mean every original decision was stupid when it was made.
When this pipeline was first created, spending weeks optimizing for documents hundreds of pages long might have been the wrong call. Startups need to move fast, and that sometimes means taking shortcuts and leaving technical debt behind. The important part is recognizing when those shortcuts stop being useful and start becoming expensive.
Premature optimization is really the root of all evil. There’s a difference between optimizing something that doesn’t need optimizing and investigating something that’s clearly broken.
The first is a waste of time. The second is engineering. Sometimes, the best optimization isn’t making your software do something faster. It’s convincing it to stop doing something stupid.